

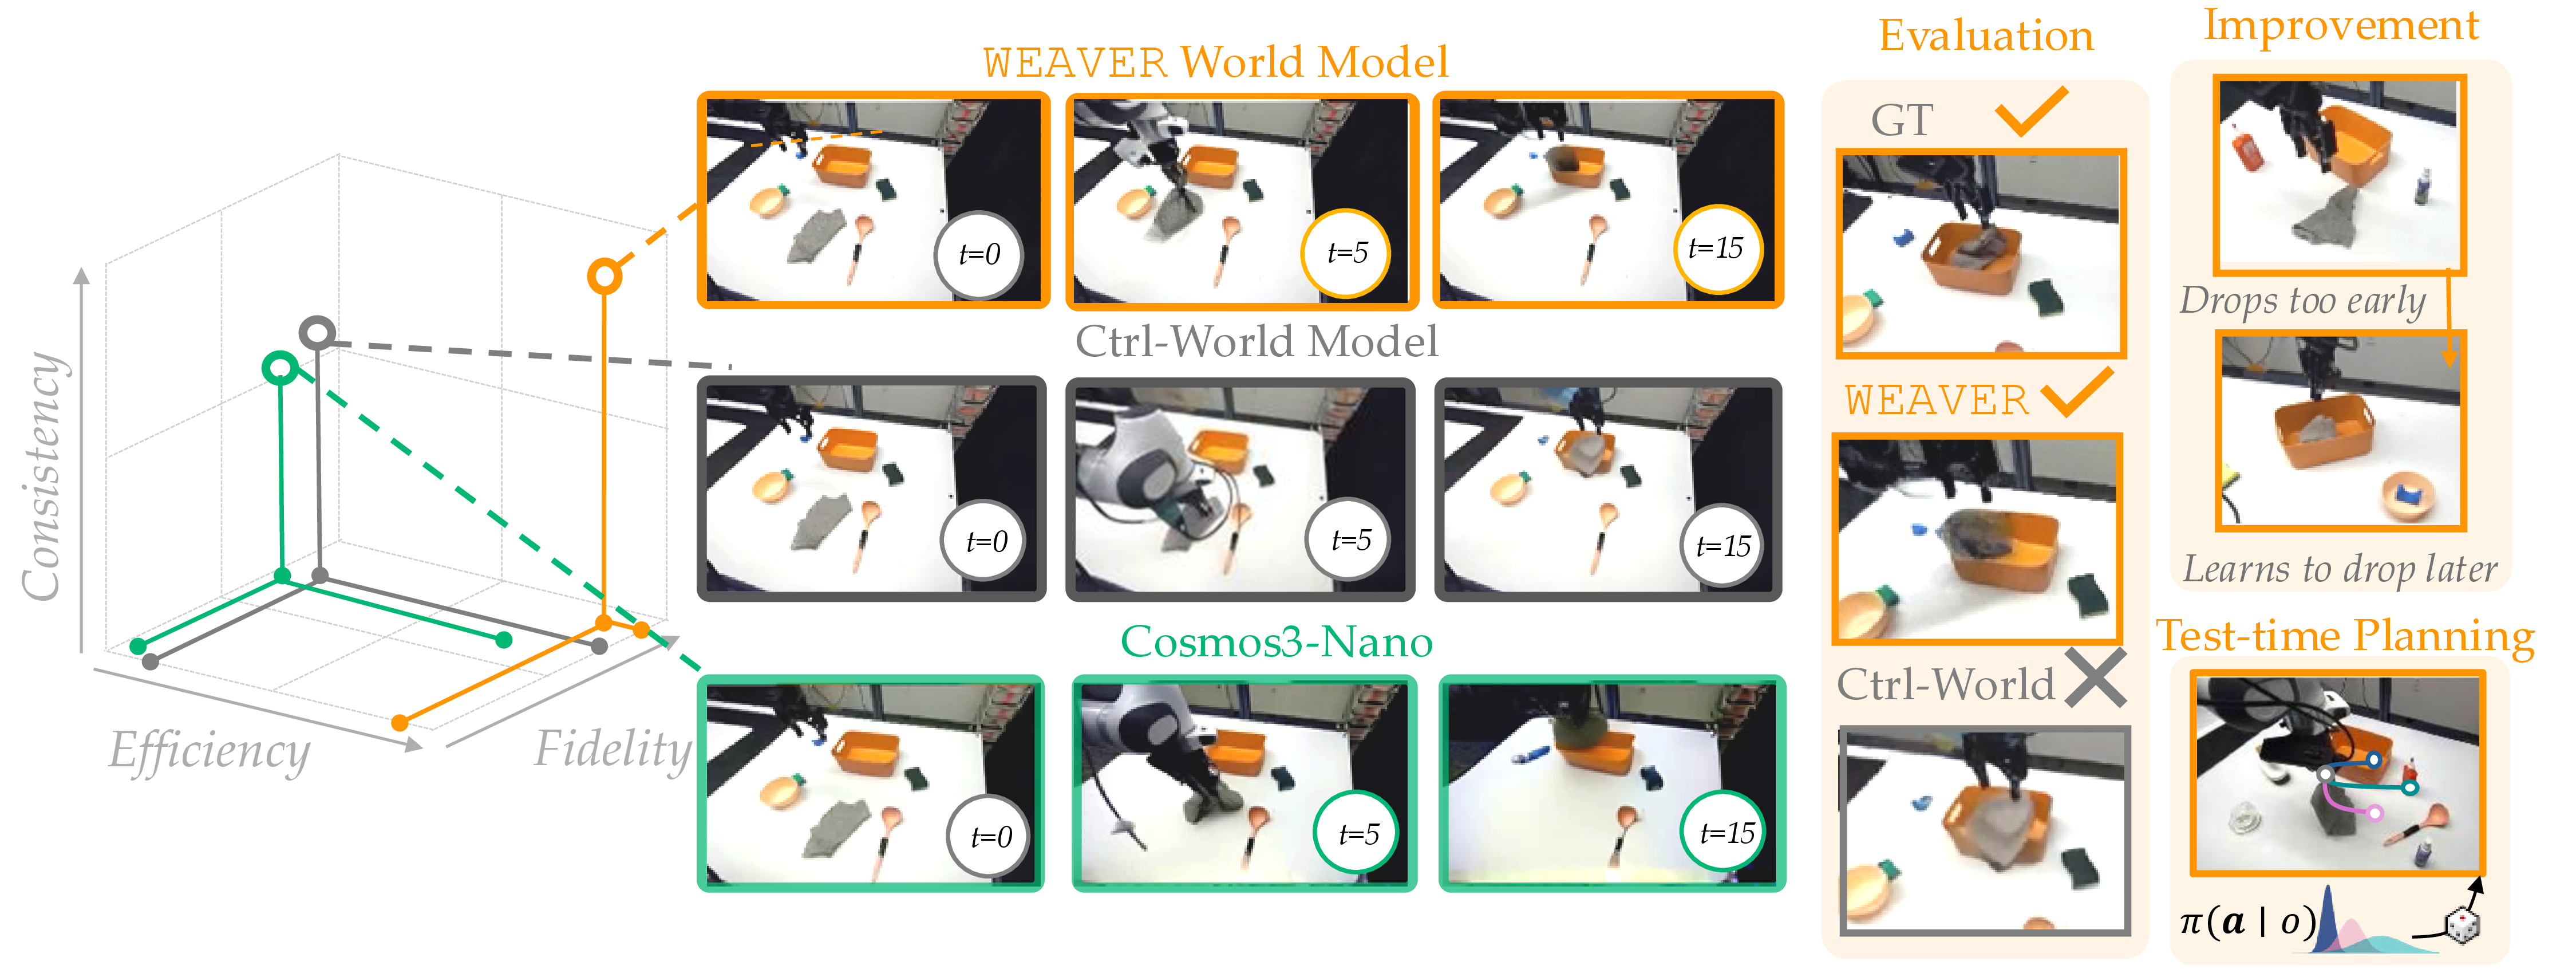
(i) Fidelity
Physically accurate predictions that correlate with reality;
WEAVER generates multiple views used by
modern visuomotor policies.
WEAVER, Better, Faster, Longer: An Effective World Model
for Robotic Manipulation
1Mila - Quebec AI Institute 2Universite de Montreal 3Carnegie Mellon University 4McGill University
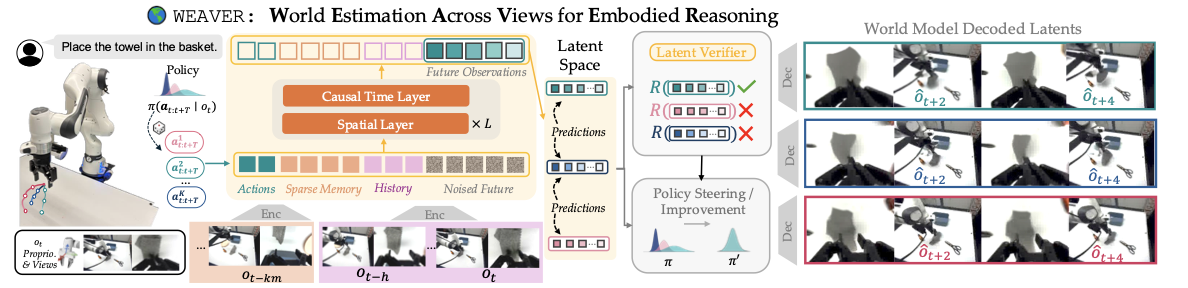
WEAVER is an action-conditioned latent world model for
long-horizon robot manipulation. It predicts future latent states,
decodes future observations when needed, and plans in latent space.
The key design decisions are:
Architecture and design. WEAVER
predicts multiple views and robot proprioceptive state. The
sparse long-term memory preserves scene context across occlusions,
short-term history captures recent motion, and an efficient
spatio-temporal Transformer generates future latents conditioned
on the action tokens.
Training and fast inference. The latent dynamics model is trained with flow matching and Diffusion Forcing, which supports consistent long-horizon prediction with different noise levels across future steps. At inference time, KV caching and rectified-flow post-training reduce the cost for planning.
Accurate reward and value estimation. To
efficiently score action chunks without decoding latents into
images or querying an external VLM judge, WEAVER
uses a lightweight reward head that operates directly on imagined
latent states and the language instruction. A critic estimates
returns beyond the imagined horizon.
WEAVER outperforms Ctrl-World and Cosmos3-Nano on DROID
validation and out-of-distribution (OOD) task data while requiring less inference time.
As we decrease the number of function evaluations (NFE) to reduce
latency, the baselines degrade substantially more than
WEAVER; WEAVER at NFE=16 matches or exceeds both
baselines at NFE=50, a 9× inference speedup. Cosmos3-Nano degrades most
with prediction horizon, likely because it lacks an explicit memory mechanism.
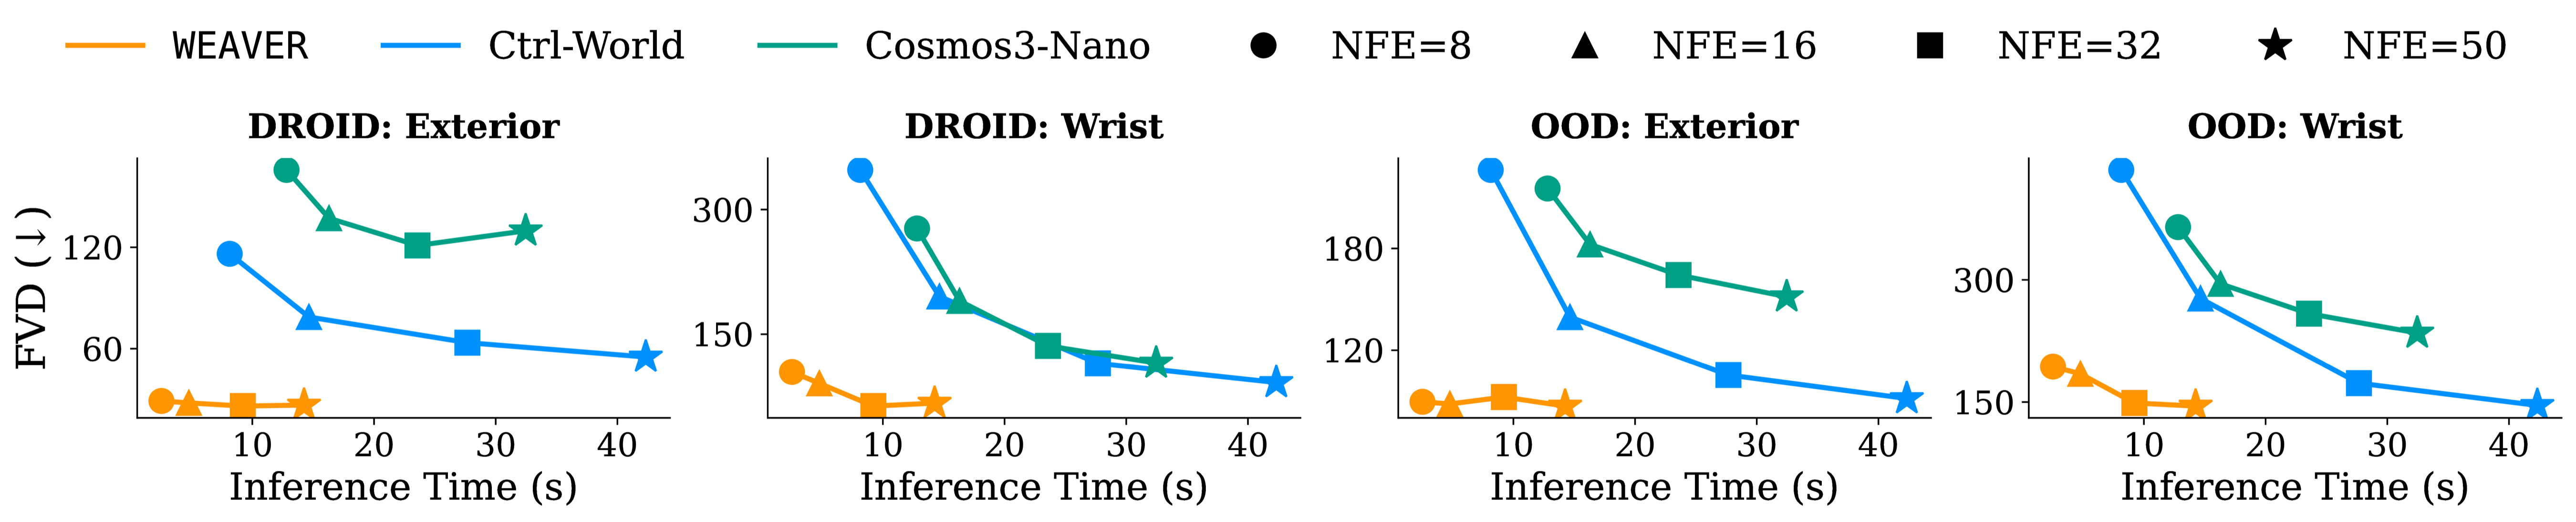
WEAVER pareto-dominates both baselines, matching or
exceeding their NFE=50 quality at NFE=16.
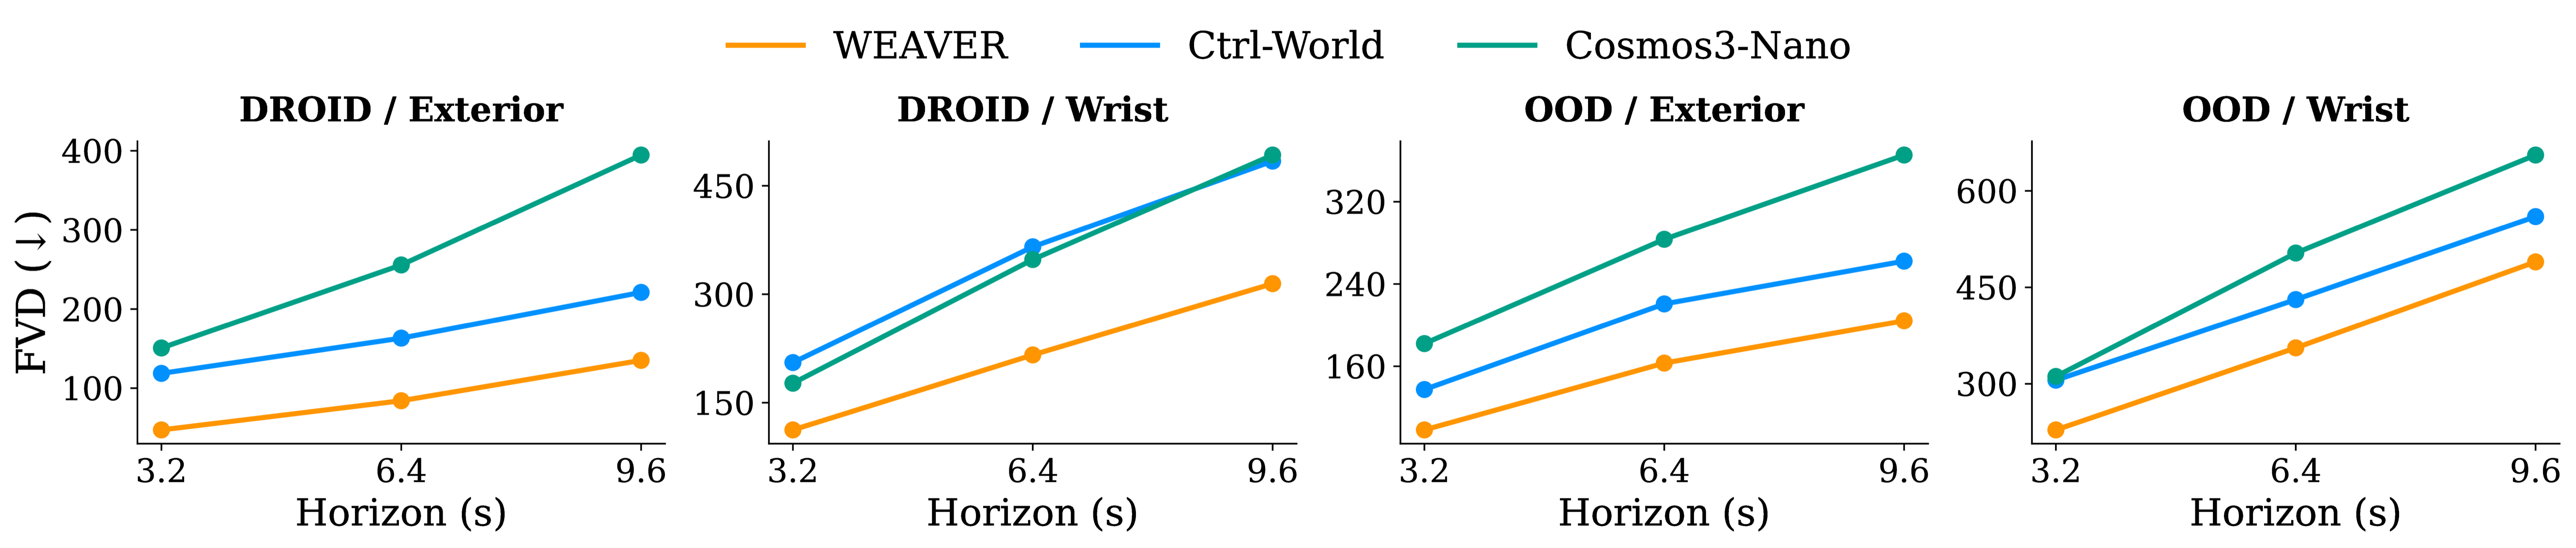
WEAVER maintains lower FVD as the prediction horizon
grows, while Cosmos3-Nano degrades most quickly.
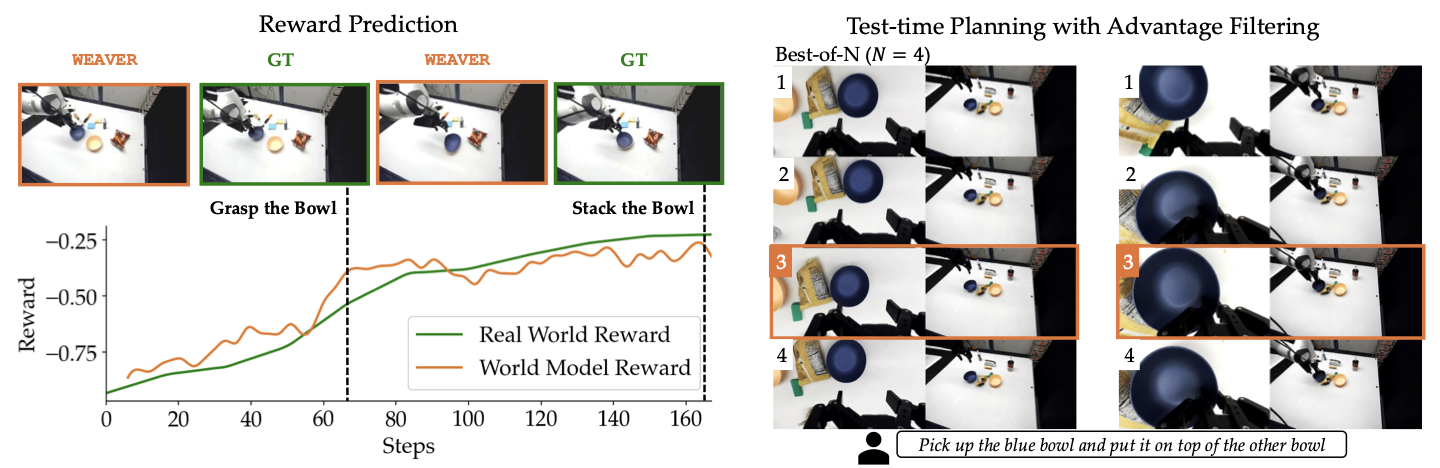
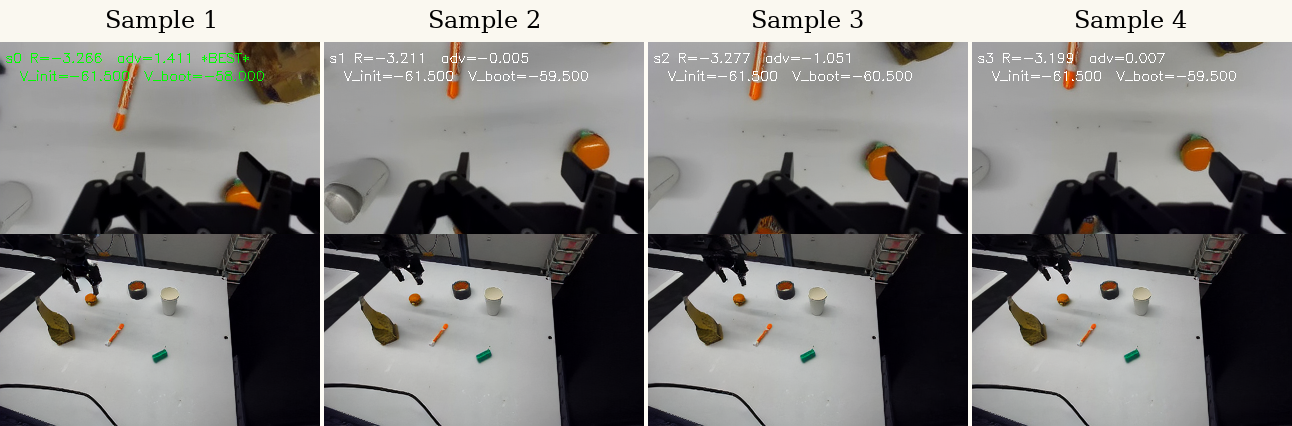
WEAVER's latent reward is trained to match RoboMeter's task progress rewards.
On OOD real trajectories, the distilled reward model can distinguish action chunks using the
predicted advantage. We observe that the segment with highest-advantage action sample corresponds
to the best imagined outcome.
By jointly satisfying (i) fidelity, (ii) consistency, and (iii) efficiency,
WEAVER supports various downstream world-model applications:
policy evaluation, policy improvement, and test-time planning.
We replay recorded real-world action trajectories open-loop in
WEAVER and label the imagined rollouts, turning the world model
into a sandbox for ranking policies without robot execution. Rollouts run up
to 40 seconds, so prediction errors compound. Pretrained world models tend to
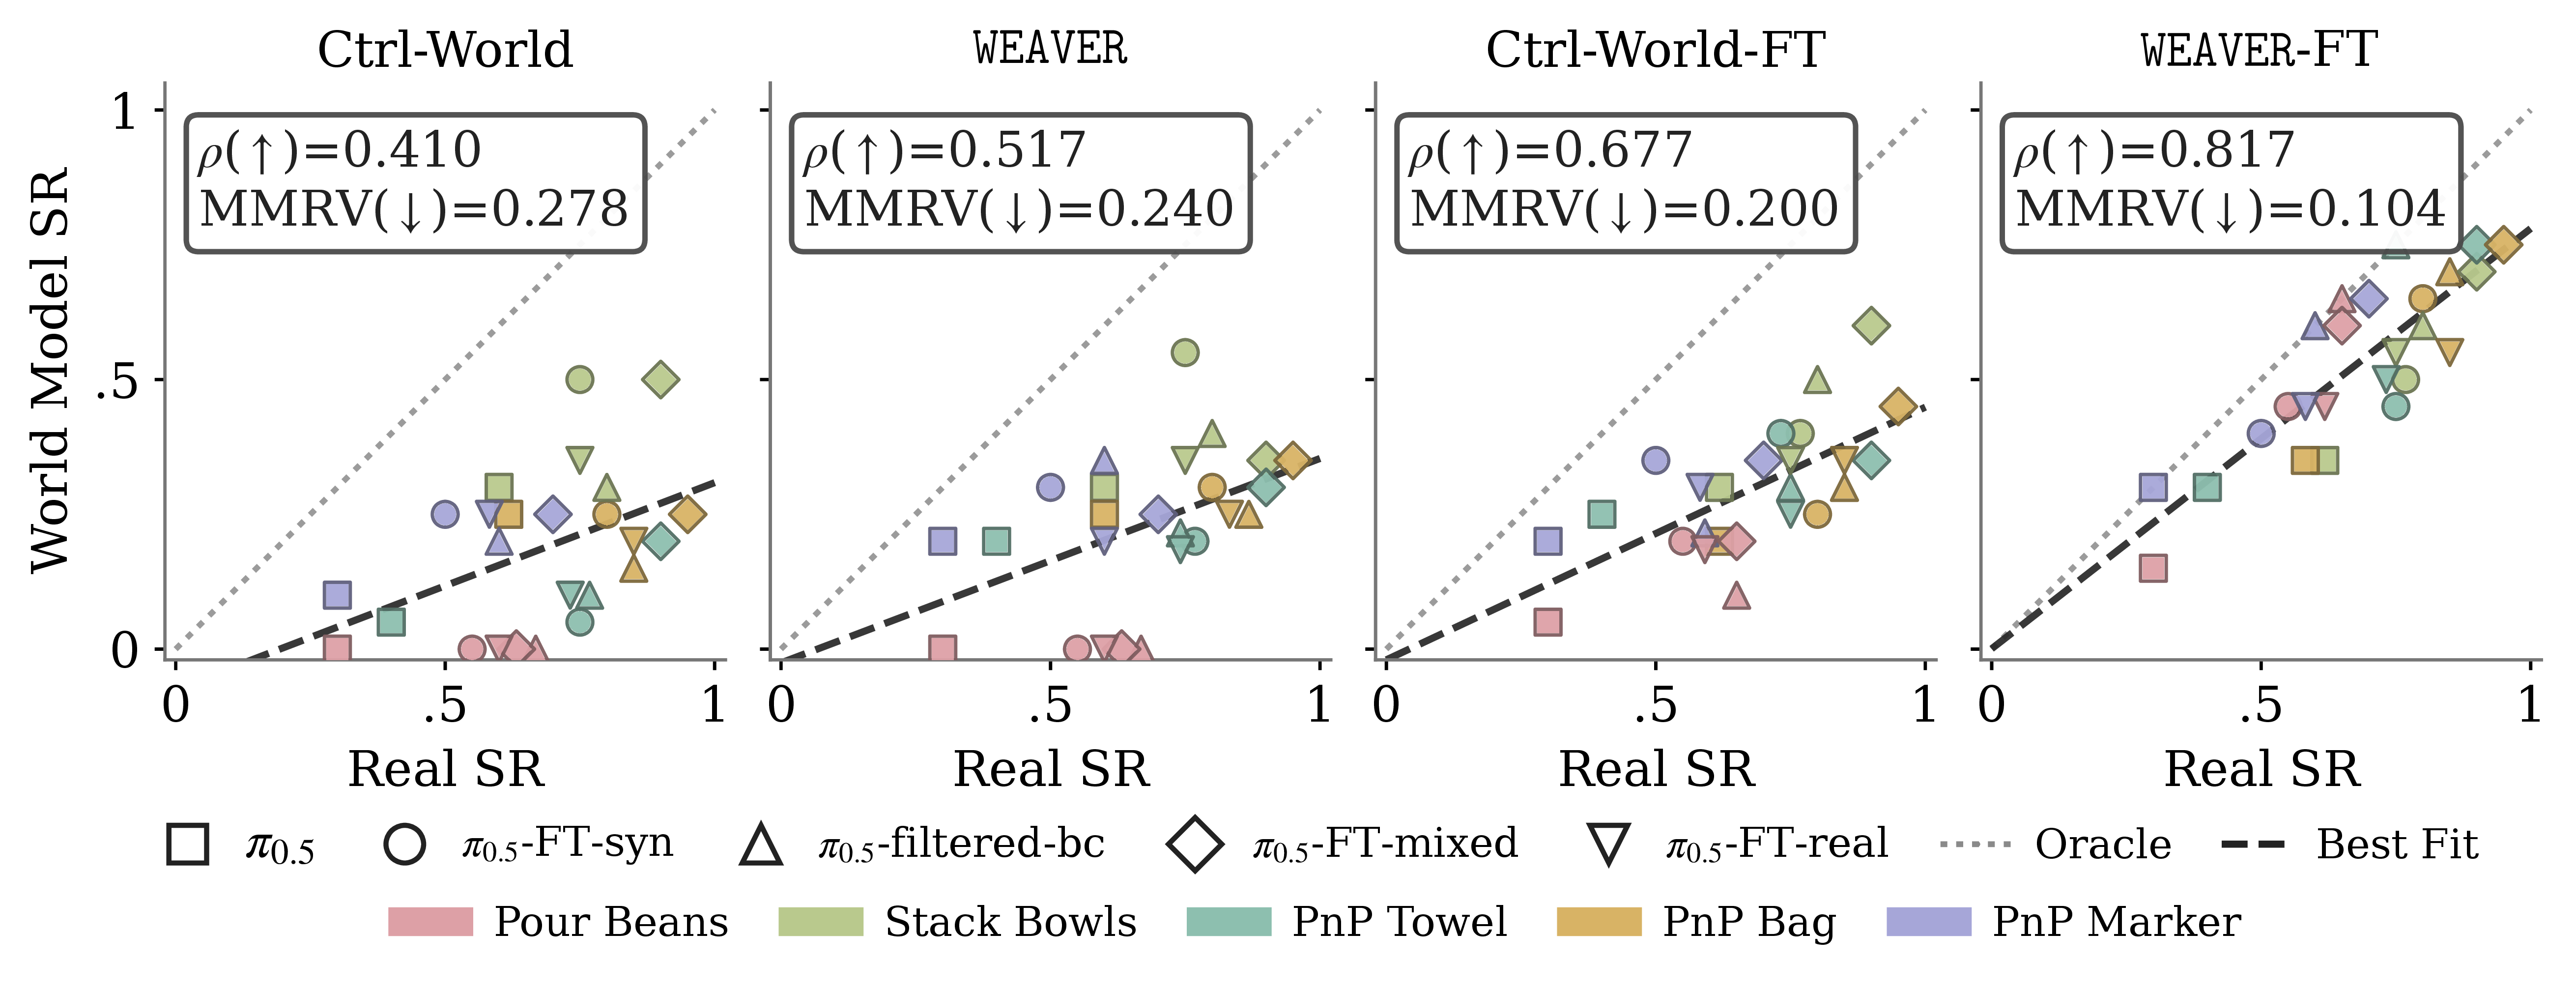
underestimate policy success; WEAVER tracks real rollouts more
closely than Ctrl-World (ρ = 0.517 vs. 0.410). This compares the two
pretrained models only — both are trained on DROID with no
task-specific finetuning.
Finetuning helps both models: WEAVER-FT leads
Ctrl-World-FT on every metric (ρ = 0.817 vs. 0.677, MMRV 0.104 vs.
0.200). In the rollouts below, only WEAVER-FT predicts the same
outcome as the ground-truth rollout from the policy on Pour Beans, Stack
Bowls, and PnP Towel: the beans scatter across the table, the bowls stack,
and the towel lands inside the basket.
For policy improvement, WEAVER samples candidate
action chunks, simulates their long-horizon outcomes, and estimates the advantage using the latent reward and critic heads. Only
high-advantage rollouts are distilled back into the base policy,
avoiding updates from plans predicted to be worse than the current
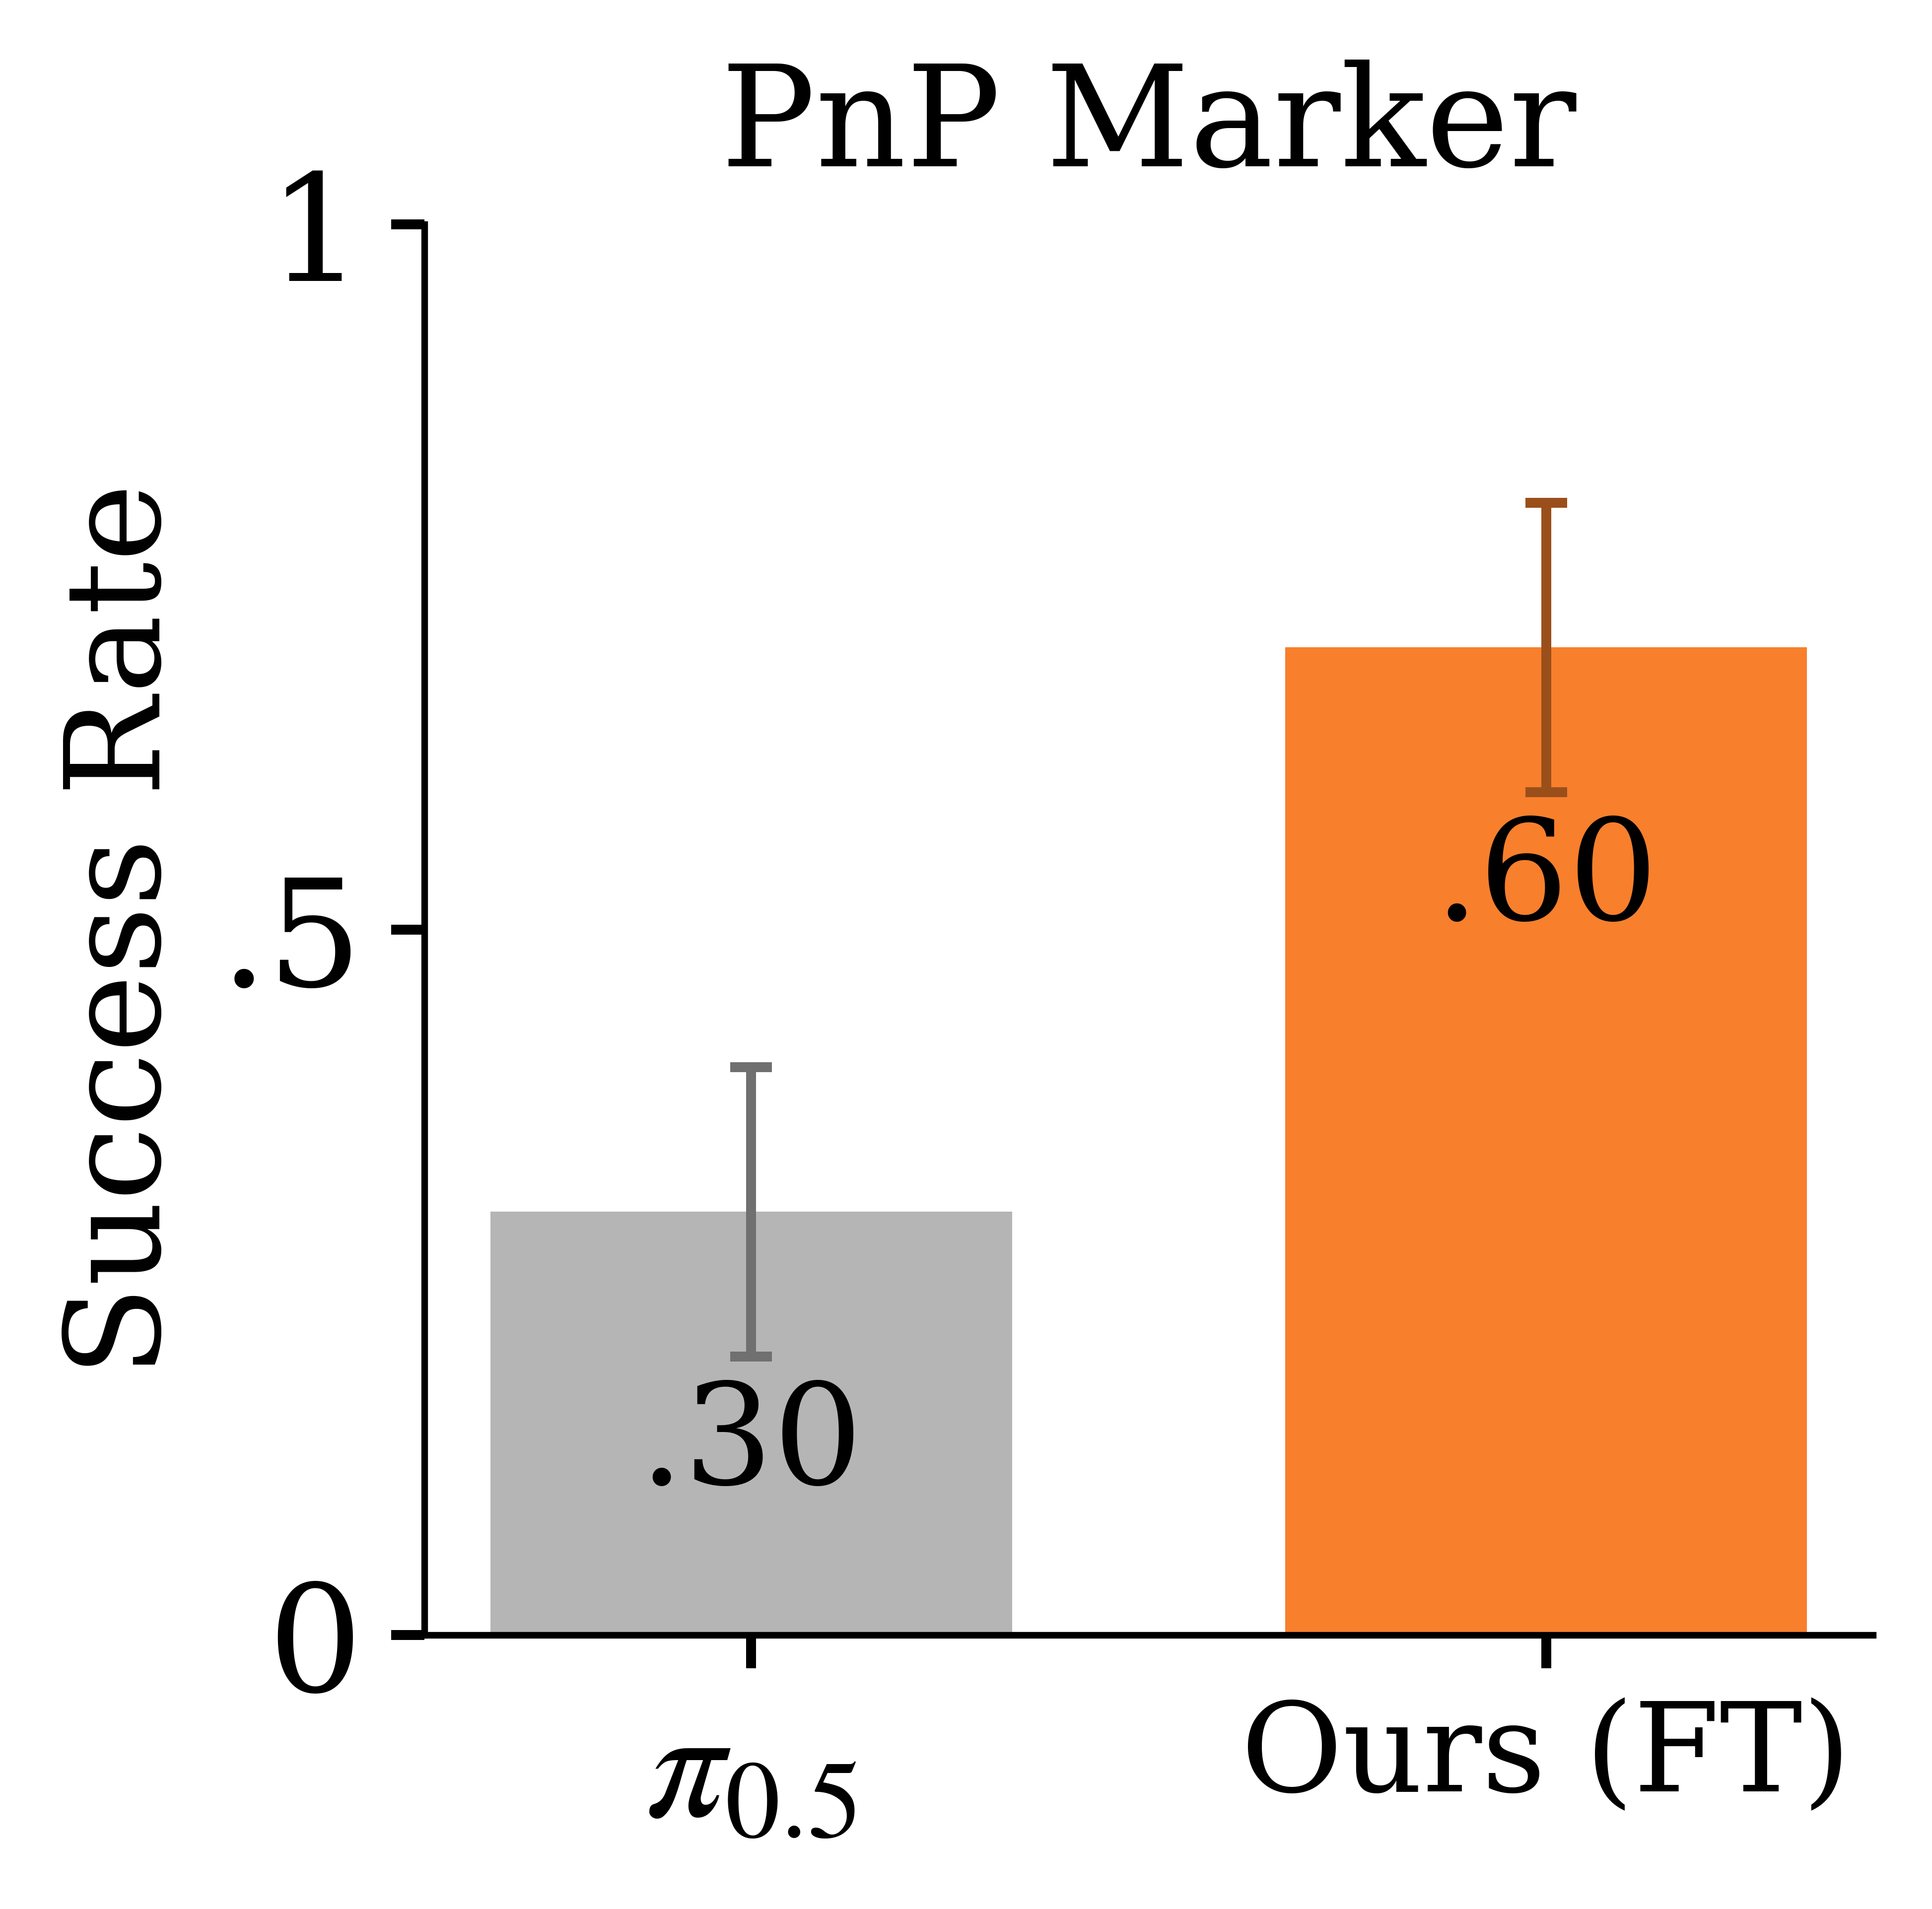
behavior. We observe that finetuning π0.5 with real and
synthetic data generated by WEAVER yields the strongest success rates.
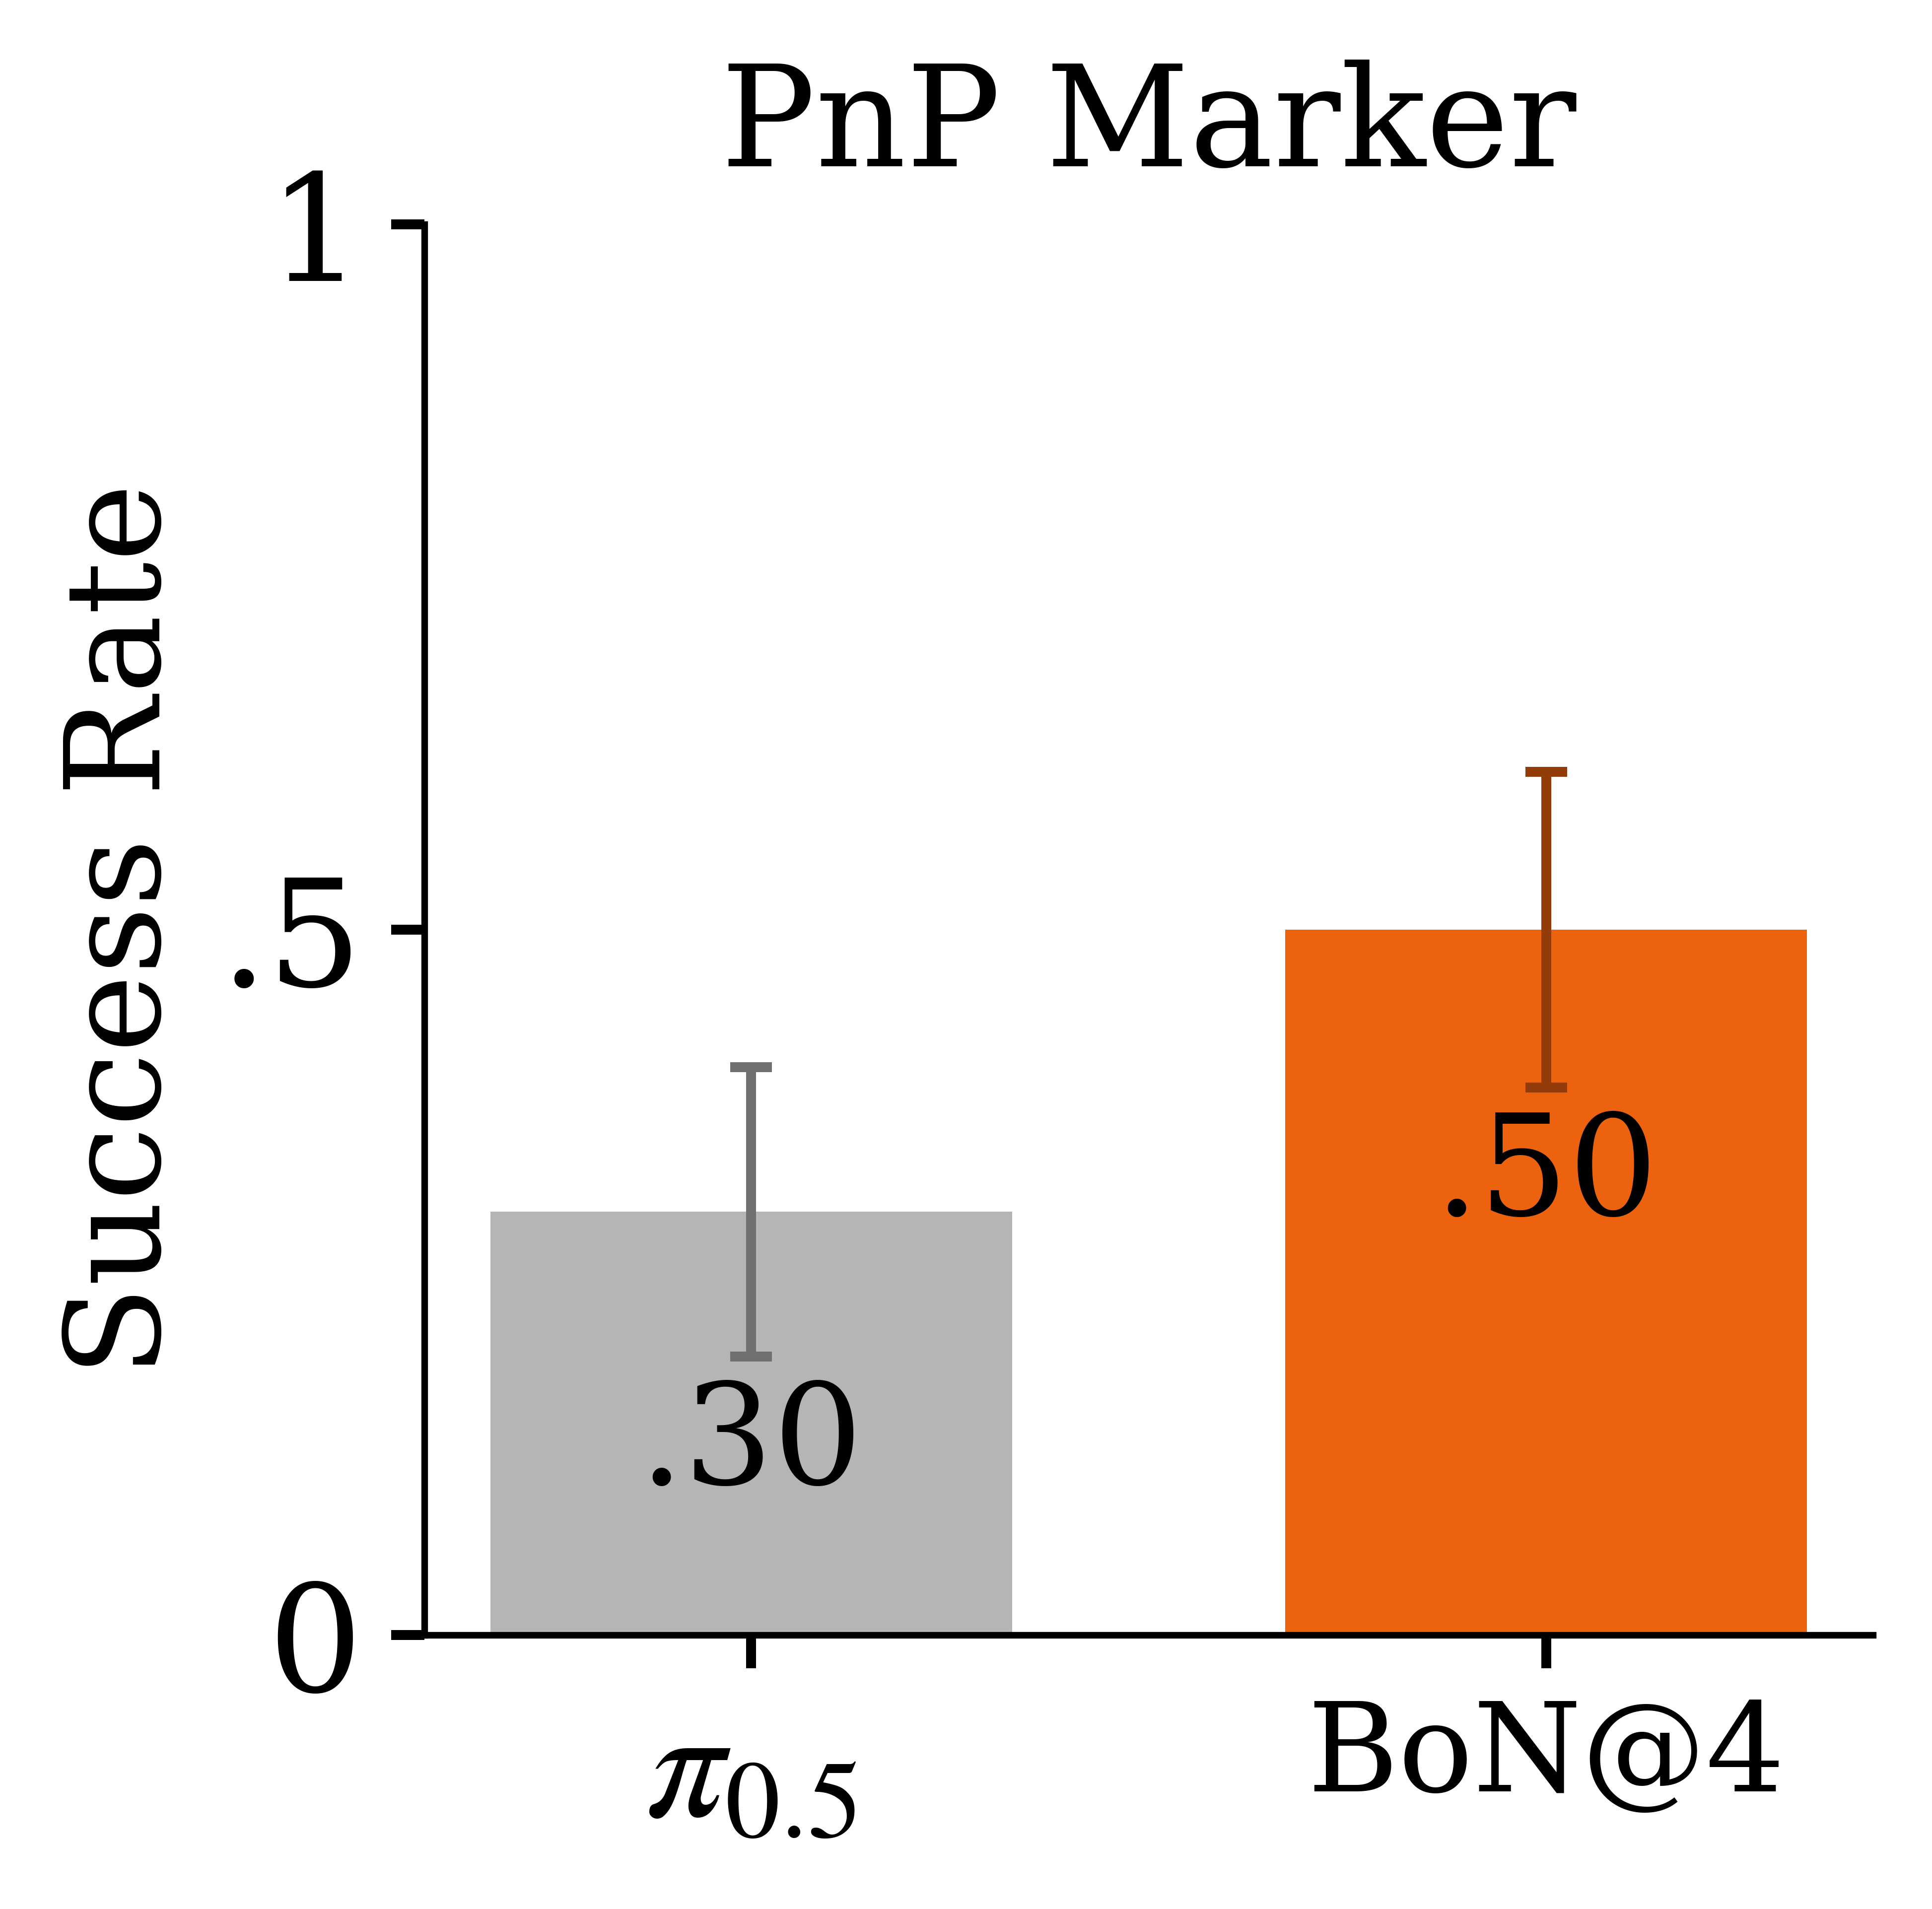
At test time, WEAVER performs single-chunk best-of-N search: it samples
multiple candidate action chunks, imagines their outcomes, and executes the one
with the highest predicted advantage. To reduce latency, we post-train the world
model with rectified flows, enabling fast latent rollouts and reward scoring.
This makes test-time planning practical without pixel reconstruction or external
VLM-as-a-judge scoring.
@article{jain2026weaver,
  title={WEAVER, Better, Faster, Longer: An Effective World Model for Robotic Manipulation},
  author={Arnav Kumar Jain and Yilin Wu and Jesse Farebrother and Gokul Swamy and Andrea Bajcsy},
  journal={Under review},
  year={2026}
}